Enterprise LLM Infrastructure

Private LLM Infrastructure That Never Leaves Your Network

Your proprietary data should not travel through someone else's API. We design, deploy and run large language models on your own servers, inside your own cloud account, or fully air-gapped, so you keep the data, the model and the cost curve under your control.

500+ projects · 85+ engineers · 30+ countries

  • On-premise
  • Private VPC
  • Air-gapped
  • Hybrid

Who this is for

Your Business Has Outgrown Public AI APIs

A processor chip lit against a dark background

Most teams start with a hosted LLM API, and for a prototype that is the right call. Then usage grows. Sensitive records start flowing through a third party's servers, the monthly token bill climbs faster than the value it creates, and compliance starts asking questions nobody can answer with a vendor's terms of service.

You also lose control in quieter ways: the model behind the endpoint changes without notice, rate limits appear at the worst moment, and latency is set by someone else's queue. That is usually the point where patching stops working and real infrastructure starts paying for itself.
Data Privacy Risk

Every prompt sent to a public endpoint leaves your network. For patient records, financials, contracts or strategy documents, that is not an acceptable default.

Compliance Exposure

GDPR, HIPAA, SOC 2 and sector rules demand data residency and access control that shared public APIs rarely give you out of the box.

Unpredictable Costs

Per-token pricing feels cheap at pilot volume. At enterprise volume it compounds. Owned infrastructure turns that into a fixed, forecastable line item.

Vendor Lock-In

When one provider's price change, rate limit or policy update can stall your product, your roadmap is not really yours. Private infrastructure gives it back.

Latency On Critical Paths

Round trips to an external API add latency to every AI-powered step. Inference close to your data and users is measurably faster for real-time workflows.

No Control Over Model Behaviour

Hosted models are updated on the provider's schedule. On your own stack you choose which model version runs, and exactly when it changes.

If two or more of these sound familiar, you are ready for private LLM infrastructure.

What we build

Enterprise LLM Infrastructure Services We Deliver

From the first GPU node to day-two operations, every layer is built for security, scale and reliability, and handed over documented.

  1. Server racks with orange network cabling in a data centre aisle

    Private LLM Deployment

    Run large language models entirely inside your own environment. No data leaves your network, no shared compute, no third-party access.

    We stand up the model on dedicated servers or isolated cloud capacity, wire in access control and connect it to your internal systems. Your team gets a private assistant that behaves like the public tools, built on open or licensed models you choose, with full data ownership.

    Best for: Organisations with sensitive data, strict compliance, or query volumes that make public APIs uneconomical.

  2. Server rack cabling lit green inside an on-premise server room

    On-Premise LLM Deployment

    Keep the model physically inside your own data centre: the highest level of control available, with no internet dependency and no cloud exposure.

    We handle GPU server configuration, model installation, inference optimisation and internal API setup. Your teams reach the LLM through a secure internal endpoint, and nothing leaves the building.

    Best for: Healthcare, finance, legal and government teams where data residency and air-gapped operation are non-negotiable.

  3. Blue network cables plugged into a cloud router switch

    VPC And Private Cloud LLM Deployment

    Not every enterprise needs its own hardware. If you already run on AWS, Azure or GCP, we deploy your LLM inside a Virtual Private Cloud, sealed off from the public internet.

    We configure the VPC, deploy the model behind private API endpoints and set network policies that block unauthorised access. You get cloud elasticity with the privacy profile of an on-premise install.

    Best for: Teams that want cloud scalability without putting AI workloads on shared infrastructure.

  4. A processor die glowing on a dense circuit board

    Open-Source LLM Hosting

    You do not have to pay per token for a capable model. Open-weight families such as Llama, Mistral, Mixtral, Qwen, Phi and DeepSeek now match commercial APIs on many enterprise tasks.

    We benchmark candidates against your real use case, pick the right one, and host it on your infrastructure with tuned inference settings: a high-performing system with no recurring API fees and full control over the weights.

    Best for: Cost-conscious enterprises, high-volume AI products, and teams that want domain models without licensing limits.

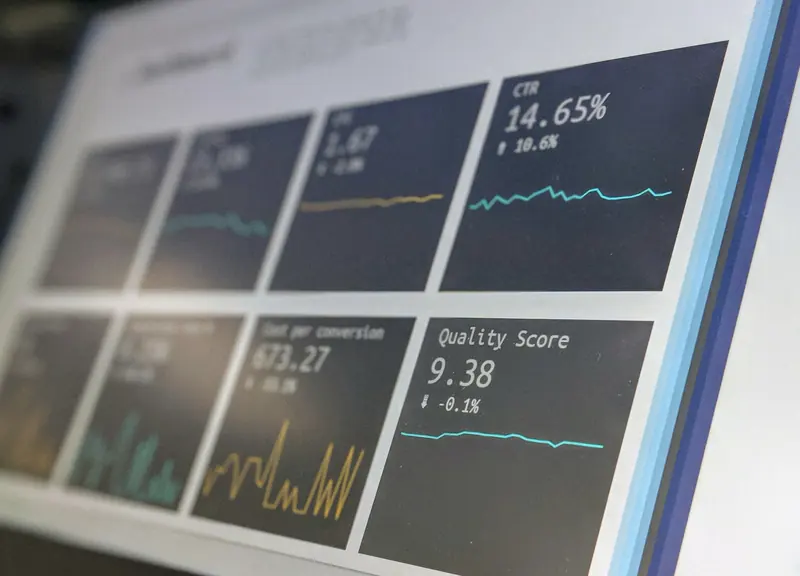
  5. Monitoring dashboard with latency and quality metrics on a screen

    LLMOps And Model Serving

    Deploying a model is the start. Running it reliably at enterprise scale takes serving infrastructure, monitoring and operational guardrails.

    We cover the production stack: serving with vLLM or Hugging Face TGI, load balancing across inference nodes, request batching for throughput, rate limiting, multi-model routing and traffic-based autoscaling, plus dashboards for latency, error rate and usage in real time.

    Best for: Organisations that need production SLAs, uptime commitments and scaling without manual intervention.

  6. A wall covered edge to edge in open book pages

    RAG Infrastructure And Knowledge Base Setup

    Retrieval-Augmented Generation lets the LLM answer from your own documents, databases and internal knowledge, without retraining the model.

    We build the whole pipeline: document ingestion and parsing, embedding generation, a vector store (Qdrant, pgvector, Weaviate or Pinecone), retrieval and re-ranking logic, and the link to your serving layer. Answers come back grounded in, and cited to, your own sources.

    Best for: Enterprises that want the LLM to work over manuals, policies, contracts or proprietary datasets, privately.

  7. Colleagues gathered around a monitor reviewing an internal tool

    Internal ChatGPT For Enterprises

    Give every team a private assistant that works like ChatGPT but runs entirely on your infrastructure, grounded in your knowledge and visible only to your staff.

    We deliver the full stack: the LLM backend, an OpenAI-compatible internal API, a chat interface people can use on day one, role-based access control, and integrations with Slack, Microsoft Teams or your intranet.

    Best for: Companies lifting productivity across HR, legal, finance, engineering and support without sending internal queries to public AI.

  8. Close-up of a processor package on a green circuit board

    LLM Fine-Tuning Infrastructure

    Fine-tuning on proprietary data needs more than a training script: it needs a secure pipeline, clean data handling, a model registry and version control.

    We build that foundation: isolated training environments, LoRA and QLoRA pipelines, experiment tracking, evaluation harnesses and a model registry, so your team can ship, compare and roll back model versions with confidence.

    Best for: Organisations with proprietary datasets that want a domain model clearly ahead of a general-purpose LLM on their tasks.

Not Sure Which Setup Fits Your Needs?

Most enterprises need more than one of these working together. We map your current systems, find where private AI pays back fastest, and recommend the right combination for your environment.

Book an Enterprise AI Assessment

Recognised & certified

  • Clutch Top Artificial Intelligence Company, UAE 2025
  • Globee Awards 2024 Bronze Winner, Technology
  • Vendorland 2025 AI Consulting
  • Clutch Top Machine Learning Company, UAE 2025
  • Corporate Vision Technology Awards 2024
  • Axiomra as seen on Tech Behemoths
  • Clutch Top Artificial Intelligence Company, UAE 2024
  • The Marfest Most Reviewed NLP Company, UAE
  • Clutch Top Artificial Intelligence Company, UAE 2023
  • Top Firms Top Web Development Company
  • TrueFirms Top AI Companies, UAE 2023

Industries we specialise in

LLM Infrastructure For Industries That Cannot Afford To Get AI Wrong

Every deployment is shaped around the data sensitivity, compliance rules and daily workflows of the sector it runs in.

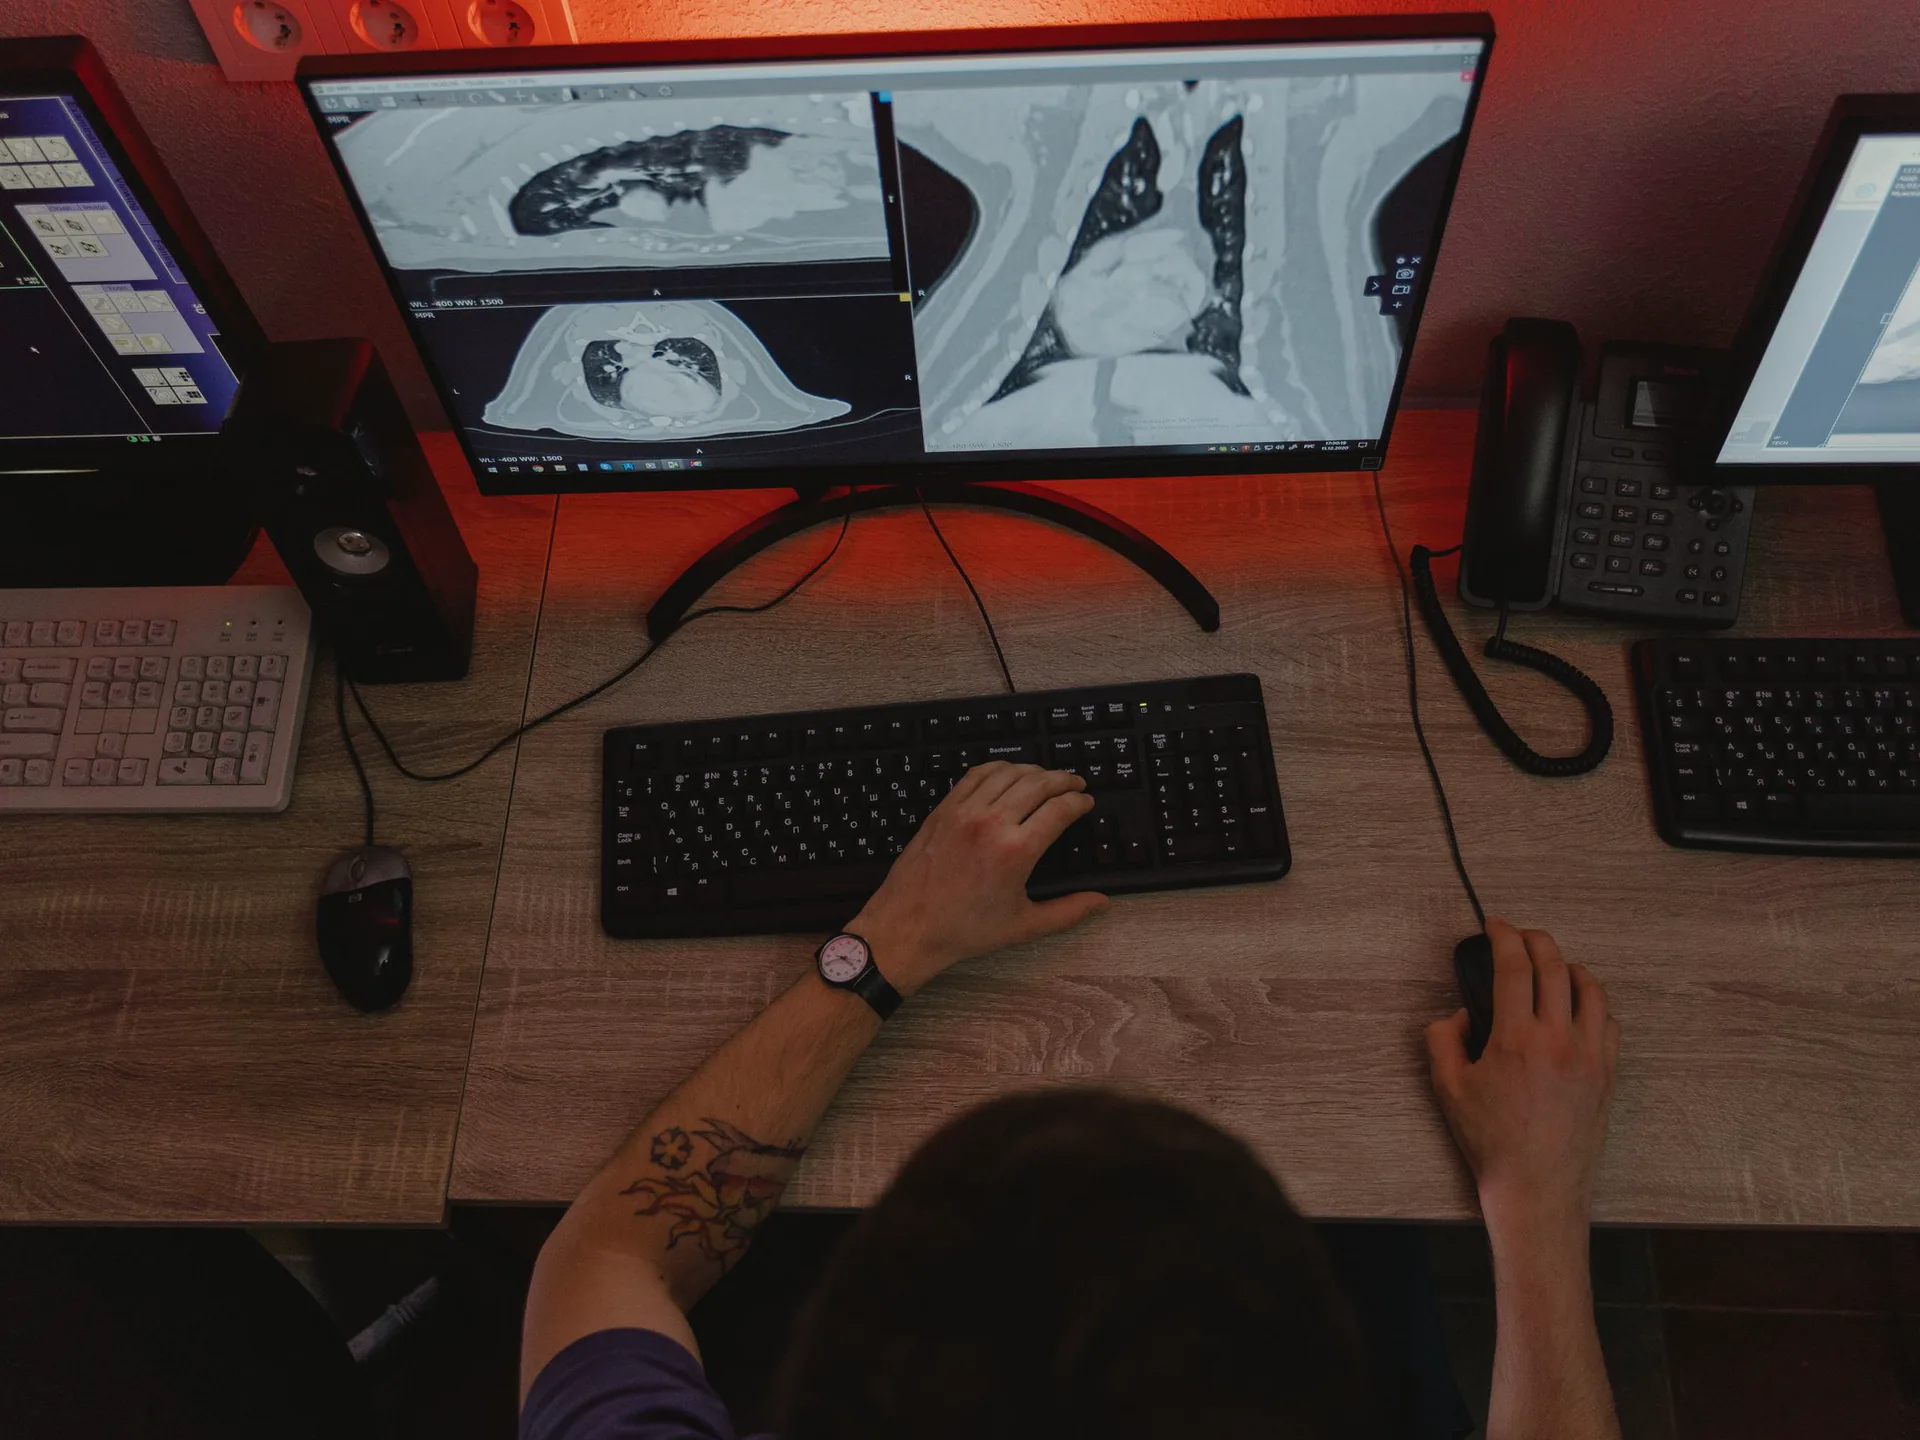
A radiologist reviewing medical scans across multiple diagnostic monitors

Private LLMs for

Healthcare

Keep patient data inside your network while giving clinical and admin teams a capable AI assistant.

  • HIPAA-aligned clinical note summarisation
  • Discharge summary and patient record drafting
  • Medical coding and billing document processing
  • Private RAG over EHR exports and clinical protocols
  • Radiology and pathology report summarisation
Explore AI for Healthcare

How we work

How Axiomra Builds Your Enterprise LLM Infrastructure

Every environment is different. The process accounts for your existing infrastructure, compliance requirements and business goals, from the first call to a fully operational LLM platform.

Step 1 of 8

Discovery And Requirements

We map your data, users, compliance obligations and the workloads you want to run, and agree what success looks like in numbers before anything is built.

What we work with

The Stack Behind Every Private LLM Deployment

Production-tested tools, chosen per project for performance, security and the environment you deploy into.

  • Llama
  • Mistral
  • Gemma
  • Qwen
  • DeepSeek
  • Claude

The Right Tools. The Right Team. Built For Your Stack.

Knowing the frameworks is table stakes. Combining them into a system that holds up in production is the job. Tell us what you want to run and we will map the architecture.

Book a Free Technical Discovery Call

Why Axiomra

What You Actually Get When You Work With Us

Rolling archive shelving units in a records room

Plenty of AI vendors will take the project. Fewer have put private models into regulated, high-stakes production and kept them healthy afterwards. Three habits separate how we work.

We scope for production from the first call, we own every layer from GPUs to the chat window, and we stay on after launch, because models drift, data shifts and usage grows in directions nobody predicted on day one.

Built For Production, Not Demos

A working notebook is not a system. Every engagement ships with evaluation, monitoring, rollback and a documented handoff, because that is where most enterprise AI stalls.

One Team, The Full Stack

Most vendors own one layer. We cover data architecture, model selection, deployment, serving and operations, so you never coordinate three suppliers to ship one system.

Engaged After Go-Live

Structured post-launch support: monitoring, re-evaluation against your golden set and proactive recommendations when performance signals change.

Projects delivered
500+
In-house engineers
85+
Countries served
30+
Partnerships
170+

What clients say

Leaders Who Trust Our Engineering

“They communicated with me and we developed trust over the years. Project management is great: the willingness to take any problem and get through it is impressive.”
Adam GawronFounder, Upstar
  • Picture Perfect
  • BULL
  • Deep Duck
  • Fashionnet
  • Fluent Talk AI
  • FormOlé
  • Front Office
  • GPT Tune

Build Your Private LLM Infrastructure With A Team That Has Done It Before

If you are handling sensitive data, hitting API cost ceilings, or working toward compliance requirements a public AI service cannot meet, this is the right conversation.

We have built private LLM platforms across regulated and high-growth industries, and we know how to get you there without unnecessary complexity or cost.

Book an Enterprise AI Assessment

Private LLMs, answered

Frequently Asked Questions

No. We can deploy into GPU capacity in your own AWS, Azure or GCP account (VPC), into a private cloud provider, or onto hardware you own. We size the options during discovery so you can compare cost before committing.